Incident propagation
On this page
When a service fails, the services that depend on it are affected too — even if their own sensors are perfectly healthy. Propagation makes this visible on the Service Map, so that you start your investigation at the root cause instead of at the first symptom.
How it works#
Onagre follows the dependencies you declared:
- A root cause is a service whose own sensors are failing (Down or Degraded).
- Every service that depends on it — directly or through other services — is impacted.
- An impacted service whose own sensors are healthy is shown as Degraded; one that is already failing on its own keeps its own status.
Nothing to configure: the computation is made each time the map is displayed, from the current state of your sensors. Loops between services are handled: each service is counted once.
Propagation is a reading aid. It does not open incidents on impacted services and does not change who is notified: incidents and notifications only come from sensors.
On the map#
Turn on Propagation in the map's toolbar:
| Indicator | Meaning |
|---|---|
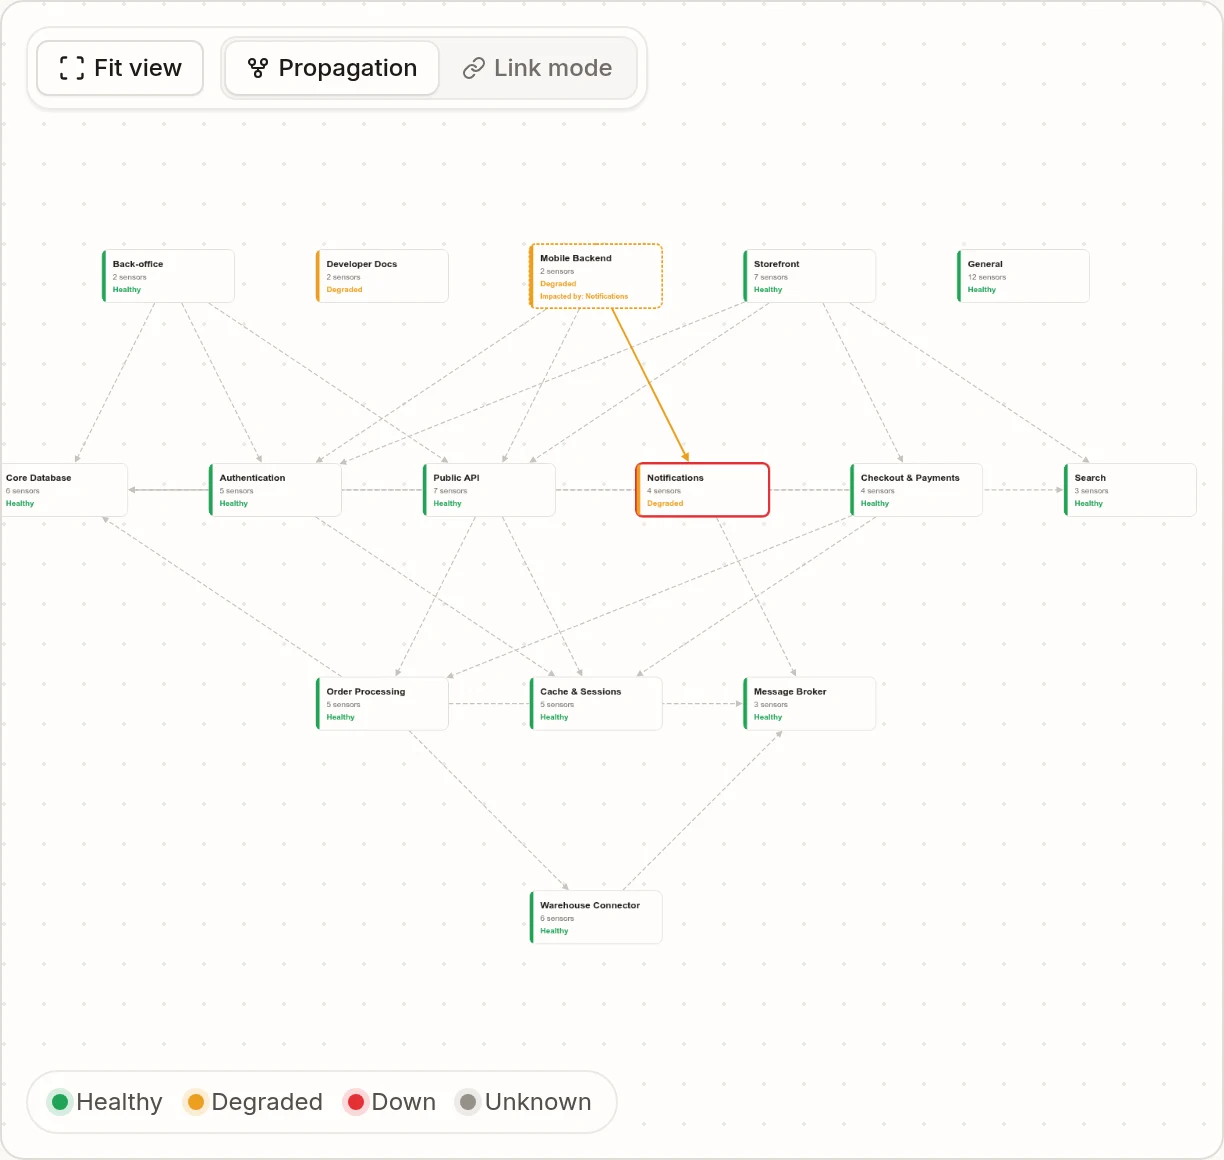
| Thick red border | A root cause that impacts other services. |
| Dashed orange border, "Impacted by …" | An impacted service, with the name of the root cause. |
| Orange arrow | The path through which the failure spreads. |
Click a service for more: an impacted service shows Impacted, its Impact source and its active incidents; a root cause shows its Downstream impact — the number of services it reaches.
Example#
On Corvane's map, the SMS provider degrades and the Notifications — SMS gateway sensor fails:
- Notifications is the root cause: one of its sensors is down;
- Mobile Backend depends on Notifications: it is impacted, although all its own sensors are up;
- Storefront, which does not depend on Notifications, stays healthy.
The team looks at the SMS gateway, not at the mobile backend.