Incidents
On this page
An incident is the record of a problem detected by a sensor: it says what failed, since when, who was notified and what the team did about it. Incidents are where you start when something is wrong — open them from Monitoring → Incidents, from a notification or from the mobile app.
When an incident opens and closes#
- It opens on the first failed check. There is no retry and no waiting period: as soon as a check fails, the incident opens with the time of that check, and the integrations linked to the sensor are notified. Server sensors are the exception: they open an incident only when a resource stays above its threshold for the configured duration.
- It stays open while the problem lasts. Onagre does not send reminders: one notification when it opens, one when it closes.
- It closes on the first successful check. The incident is resolved automatically, its duration is recorded, and a recovery notification goes to the same integrations. There is nothing to close by hand.
A sensor has at most one open incident at a time. Deleting a sensor closes its open incident ("Closed — resource deleted"); pausing it, or a maintenance window, stops the checks and therefore leaves an open incident open until checks resume.
Severity#
Each incident carries the severity of its sensor: Critical, Major, Minor or Info. It is set on the sensor (Schedule and severity) and lets you sort and filter incidents by importance. It does not change who is notified: that is the sensor's alerting.
Acknowledge an incident#
To acknowledge an incident is to tell the team "I'm on it". Click Acknowledge on an open incident and say what you are doing in What are you doing about it? (at least 5 characters).
The incident becomes Acknowledged and your comment joins its activity. Acknowledging does not stop the checks, does not resolve the incident and sends no notification: the incident still closes by itself when the check succeeds. It simply avoids two people investigating the same problem without knowing it.
Acknowledging and commenting require the User role. From the mobile app, acknowledging adds the comment "Acknowledged from mobile".
The incident page#
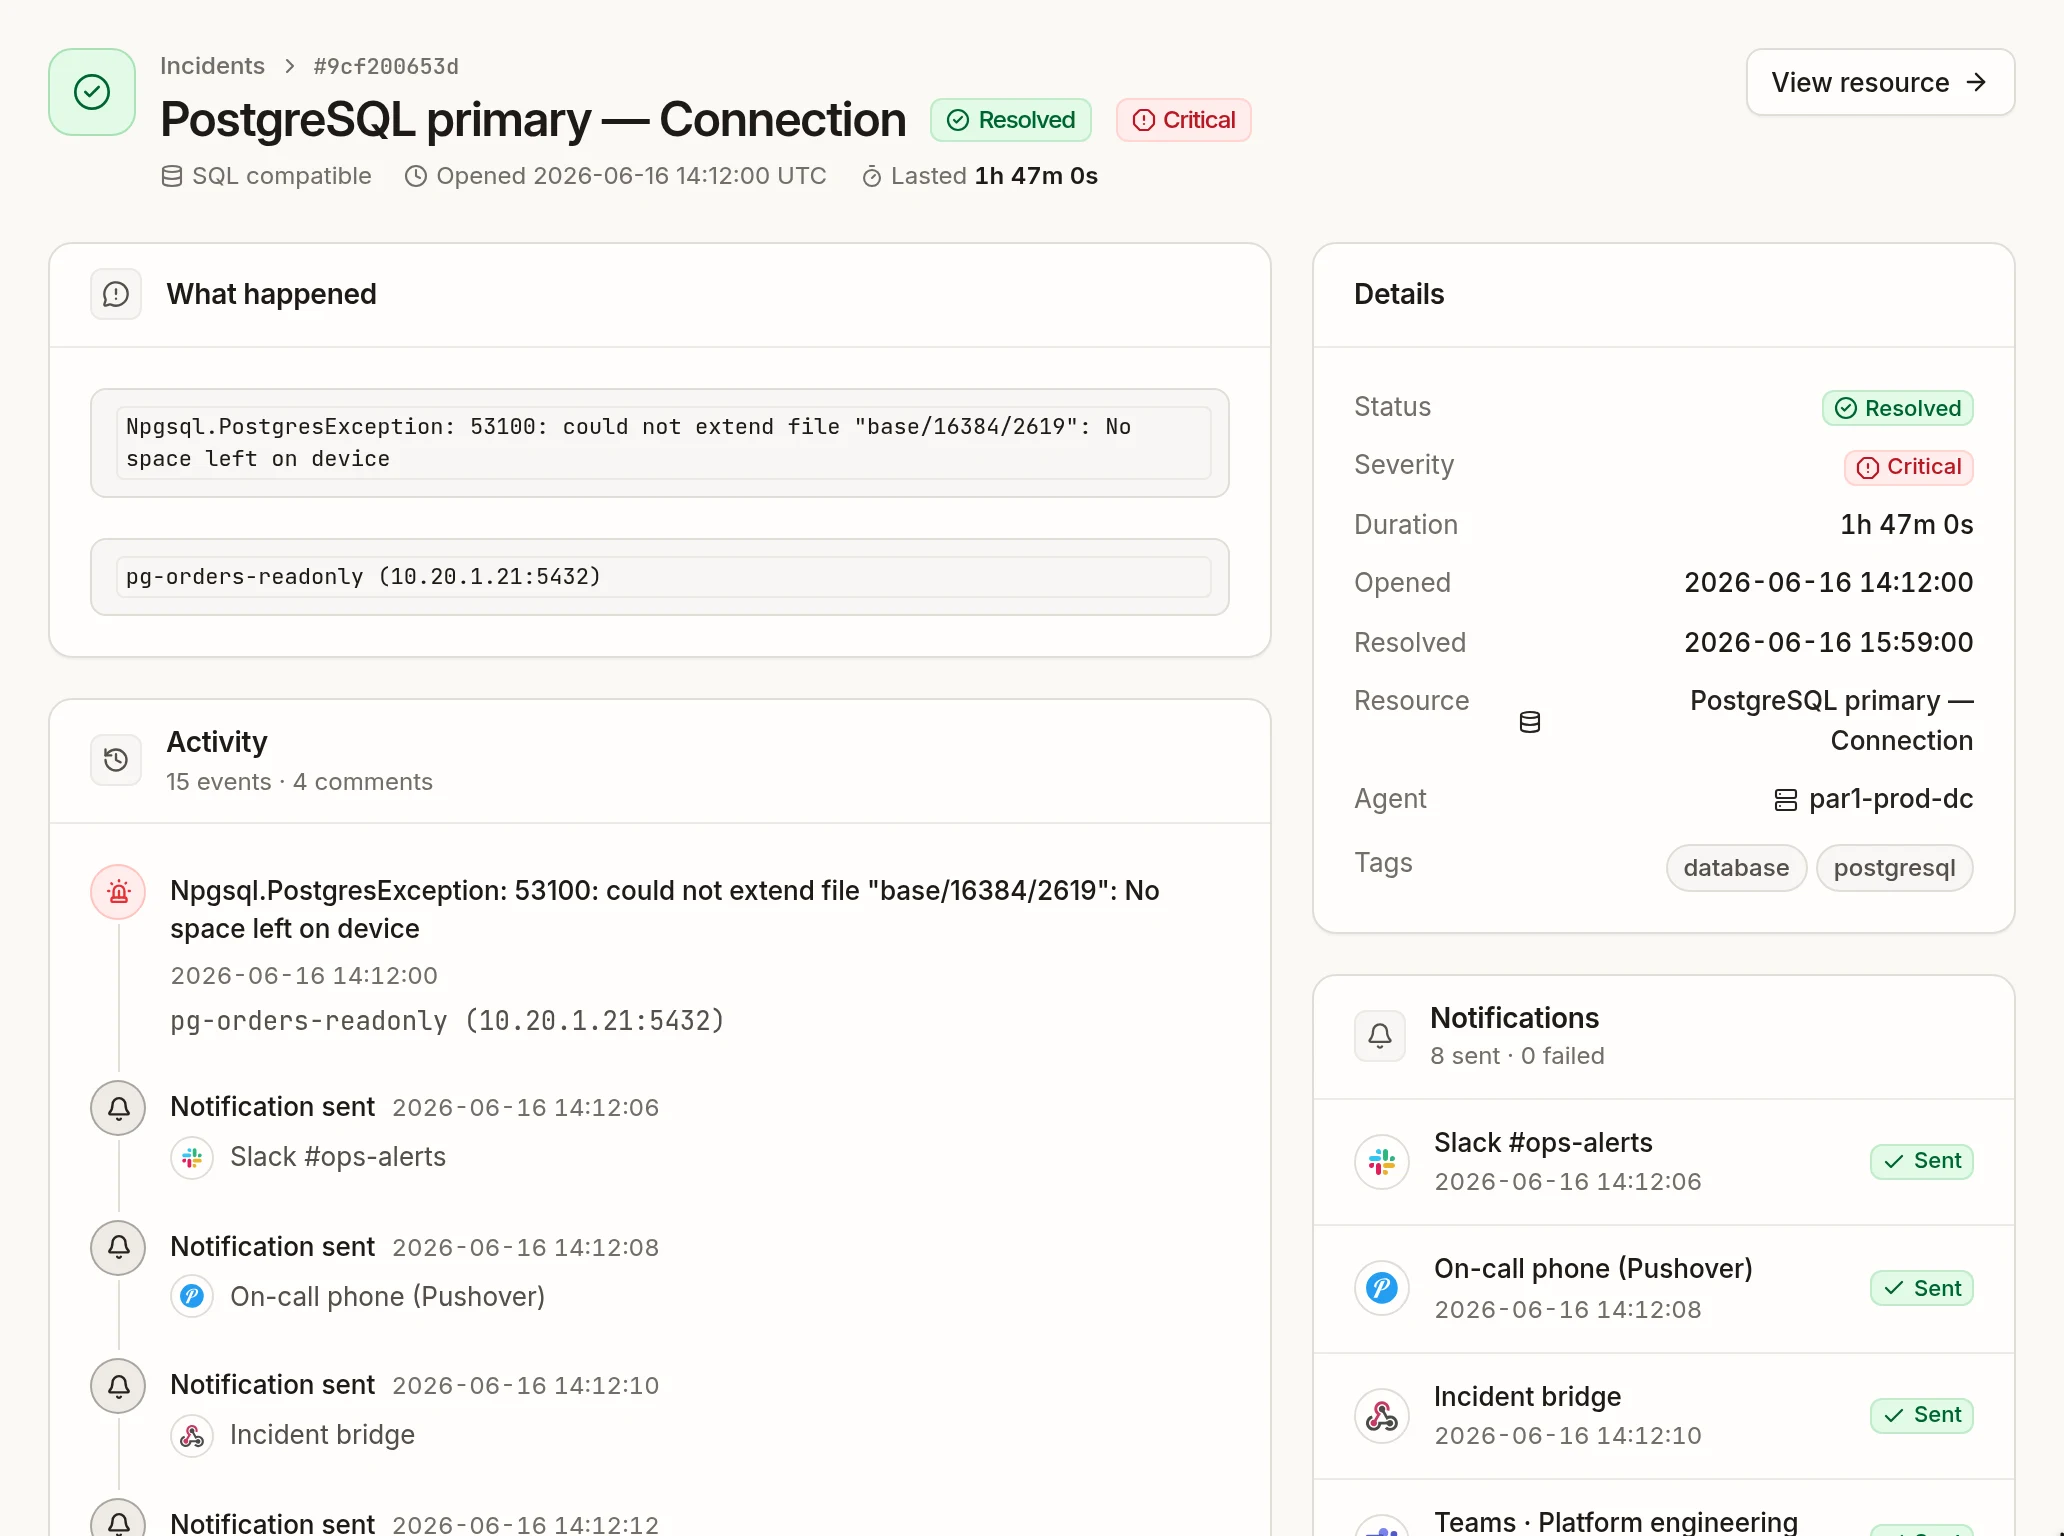
- Header — the sensor, the status (Open, Acknowledged or Resolved), the severity, when it opened, and how long it has lasted. View resource opens the sensor.
- What happened — the error reported by the check: an HTTP status, a timeout, a database error, an unexpected value…
- Details — status, severity, duration, opening and resolution times, sensor, agent and tags.
- Activity — everything that happened, in order: the failure, each notification sent (or failed), the acknowledgement, the team's comments, the resolution.
- Notifications — every integration notified, marked Sent or Failed.
- Dependencies — the other sensors that depend on the failing one, with their current state, to assess the impact.
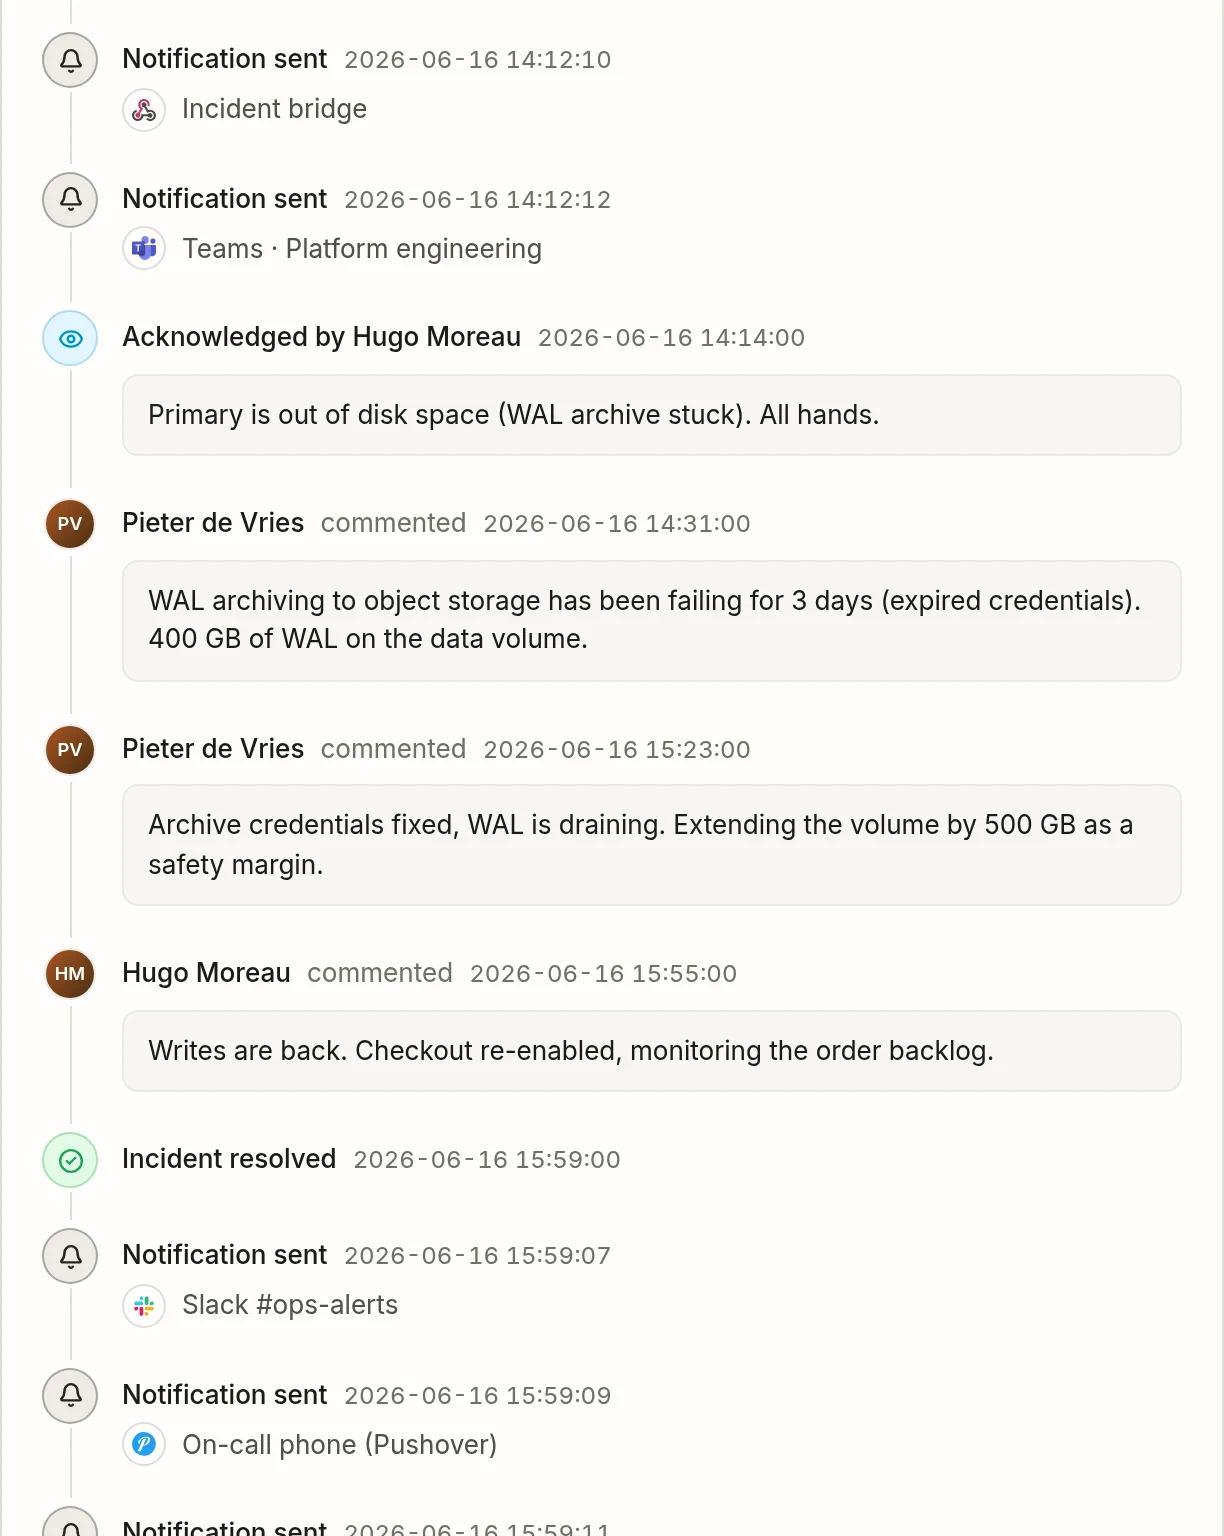
Anyone with the User role can add a comment — progress, findings, a link to the post-mortem — at any time, including after resolution.
The incidents page#
Monitoring → Incidents covers the last 30 days.
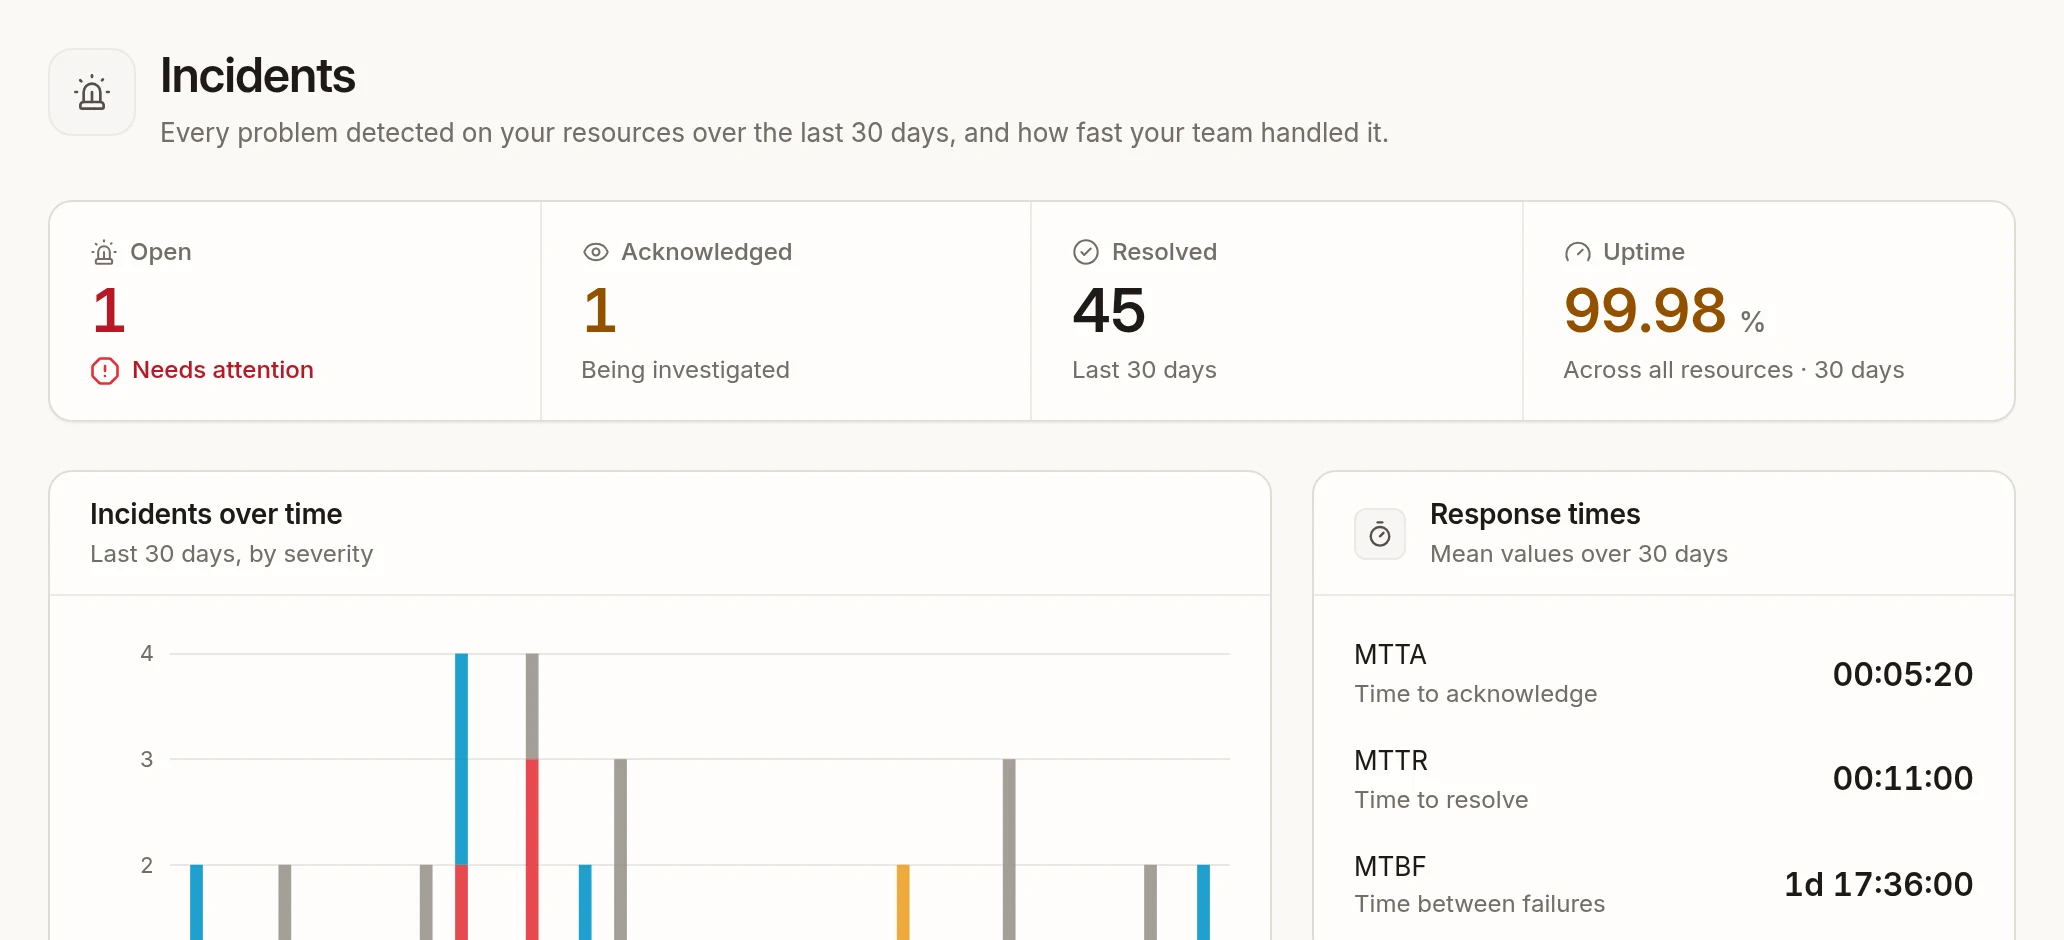
- Open, Acknowledged, Resolved and Uptime across all sensors.
- Incidents over time — incidents per day, by severity.
- Response times — the team's averages over 30 days:
- MTTA, time to acknowledge: from opening to acknowledgement;
- MTTR, time to resolve: from opening to resolution;
- MTBF, time between failures: how often sensors fail.
- Longest downtime and Most incidents — the five sensors that suffered most.
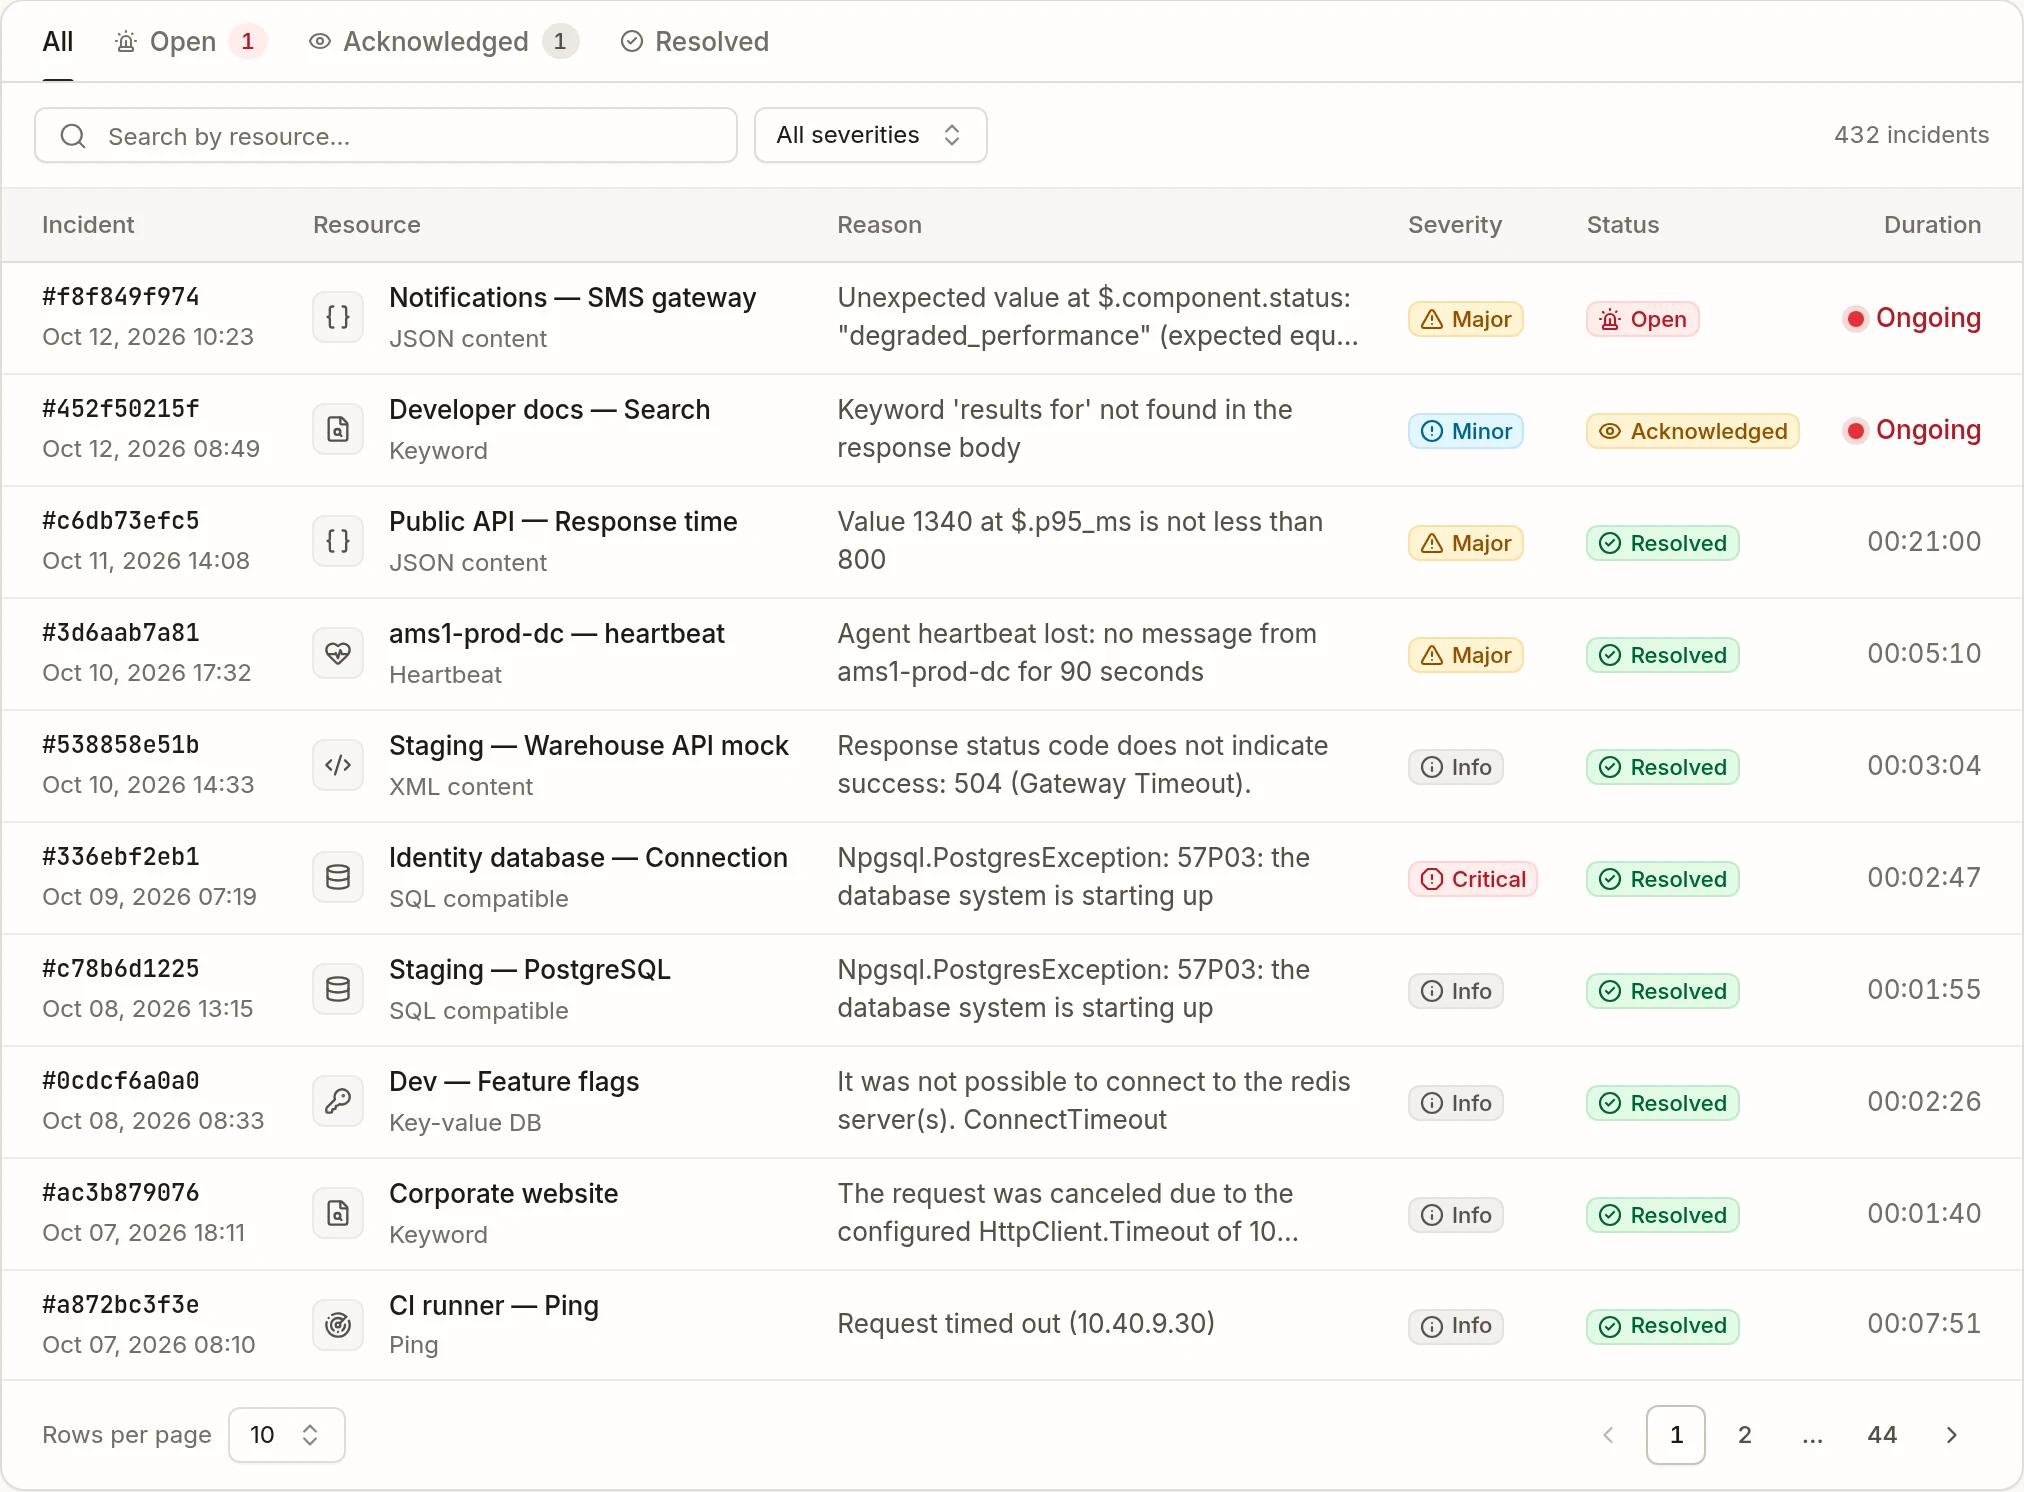
The list below can be filtered by status (All, Open, Acknowledged, Resolved), by severity and by sensor name, 10, 25 or 50 per page.
Related#
- Alerting and notifications — who receives what, and when.
- Incident propagation — how a failing service affects the services that depend on it.
- Maintenance windows — avoid incidents during planned work.